

“We were very happy with the quality of the data that we purchased. It will assist our efforts to improve our product. The team at Unidata was very responsive to our needs, and provided the data format needed to complete our tasks. We are happy to state that Unidata delivers a high quality product in an effective and efficient manner.”
Commercial
Kids & Teens Aging Dataset (Ages 7-21)
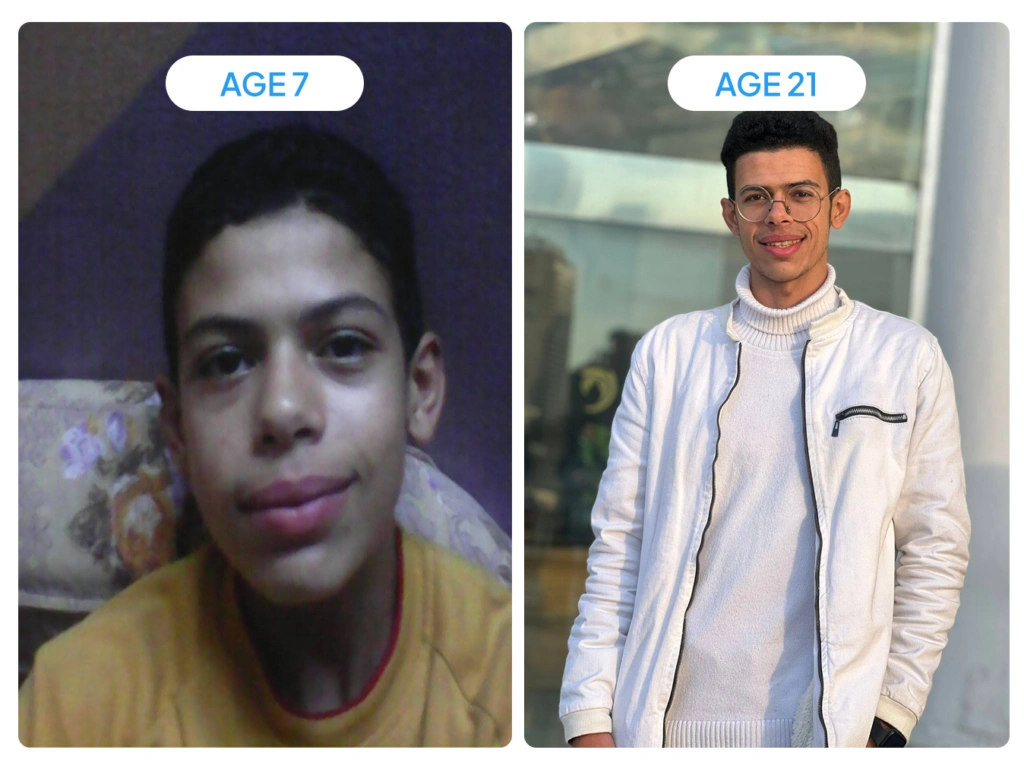
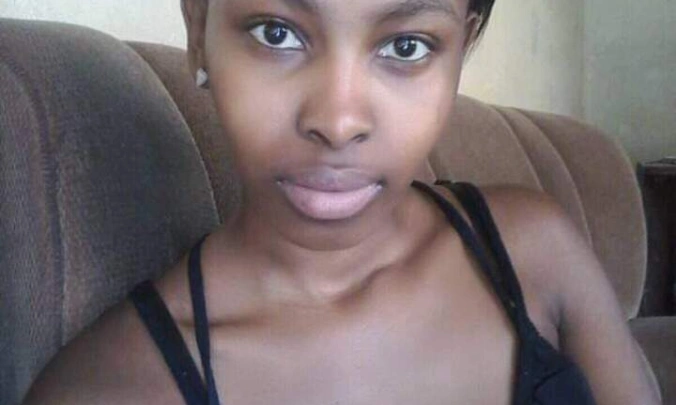
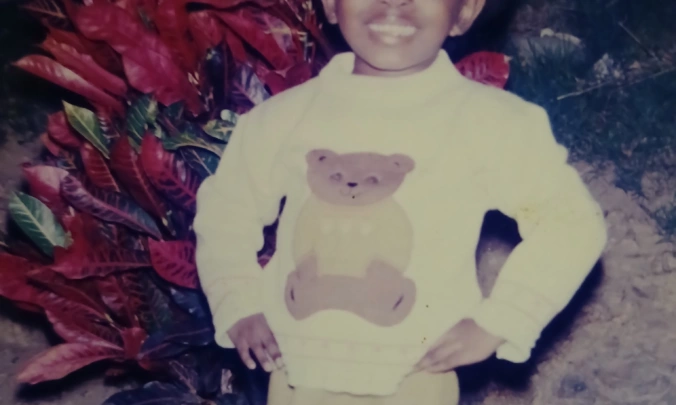
The dataset was created for age estimation, age progression analysis, and facial aging studies in children and teenagers aged 7–21. This face image dataset includes photos annotated with the Monk Skin Tone (MST) scale, camera angle, whether the shot is a digital or physical (scanned) photo, accessories worn, blur, and background handling, alongside demographic metadata (gender, ethnicity, skin tone category).
-
- Photos
- 8,039
-
- People
- 536
- Facial Recognition
- Age Estimation
- Re-identification
- Security
- Computer Vision
- Facial Recognition
- Age Estimation
- Re-identification
- Security
- Computer Vision
The dataset was created for age estimation, age progression analysis, and facial aging studies in children and teenagers aged 7–21. This face image dataset includes photos annotated with the Monk Skin Tone (MST) scale, camera angle, whether the shot is a digital or physical (scanned) photo, accessories worn, blur, and background handling, alongside demographic metadata (gender, ethnicity, skin tone category).
- Facial Recognition
- Age Estimation
- Re-identification
- Security
- Computer Vision
-
- Photos
- 8,039
-
- People
- 536
Dataset Info
| Characteristic | Data |
| Description | Photos of children and teenagers for age progression analysis. Each photo is annotated with the Monk Skin Tone (MST) scale |
| Data types | Image |
| Tasks | Face recognition, Computer Vision, Biometric Verification |
| Total number of images | 8,039 |
| Total number of people | 536 |
| Number of files in a set | 14-15 |
| Labeling | Only technical characteristics and metadata (age, age_months, gender, ethnicity, skin, mst, camera_type, is_digital, accessories, blur, background_processing, people_on_the_background) |
| Gender | Female, Male |
| Ethnicity | Caucasian, Asian, African, Hispanic, South Asian, Middle Eastern |
| Skin tone category | Light, Medium, Brown, Dark |
| Age | 7-21 |
Fintech hit by 100K biometric spoofing attacks monthly
Discover how top fintechs prevent fraud — download our free white paper
Technical
Characteristics
| Characteristic | Data |
| Image extensions | JPG, PNG, webp 4 |
| Camera type | Back, Front |
Statistics
- Distribution by gender
- Distribution by ethnicity
- Distribution by skin tone
- Distribution by Monk Skin Tone
- Distribution by accessories (by photo, top values)
- Distribution by camera type
- Distribution by background processing (by photo)
Dataset Use Cases
FAQs
Can I request a sample of the Kids & Teens Aging Dataset before purchasing?
Yes, you can request a sample of the Kids & Teens Aging Dataset before purchasing the full collection. Free samples are available for trial and testing, allowing you to assess image quality, age labels, metadata structure, and suitability for your age estimation models.
What types of annotations are provided in this age estimation dataset?
The dataset provides technical metadata and demographic annotations, including age, age in months, gender, ethnicity, skin category, Monk Skin Tone (MST), camera type, and image characteristics. Additional fields include accessories, blur, background processing, whether people appear in the background, and whether an image is digital.
How many images and participants are included in the dataset?
The dataset contains 8,039 images from 536 individuals, with approximately 14–15 files per set.
What is the Monk Skin Tone scale, and how is it used in this dataset?
The Monk Skin Tone (MST) scale is a framework for categorizing skin tones, and the dataset description specifies that each photo is annotated using this scale. These annotations can support research into model performance across skin tones and help identify potential disparities in facial analysis and age estimation.
Which ethnic groups are represented in kids & teens aging dataset?
The dataset’s ethnicity metadata includes Caucasian, Asian, African, Hispanic, South Asian, and Middle Eastern categories.
How are Unidata datasets licensed?
Unidata datasets follow a dual-licensing model: free samples are provided for trial and testing, while complete datasets are available exclusively through purchase. This approach allows users to assess a dataset’s suitability before purchasing the full collection.
How are Unidata datasets stored?
Unidata stores all datasets securely on AWS cloud infrastructure, supporting high availability and scalability. Its storage and management practices are aligned with ISO 27001 and ISO 27701 standards for information security and privacy management.
How long does it take to receive the dataset?
After you submit a request, Unidata will contact you to review the requirements and complete the necessary documentation. Following signing and payment, the dataset will be delivered within 3–10 days.
Still have questions about using Unidata datasets?
Read our user-guides
Unidata Cases
Digital Tree Passport Annotation for Forest Mapping
- Forestry Monitoring & GIS
- 200,000 trees, 10 species classes
- 2 months
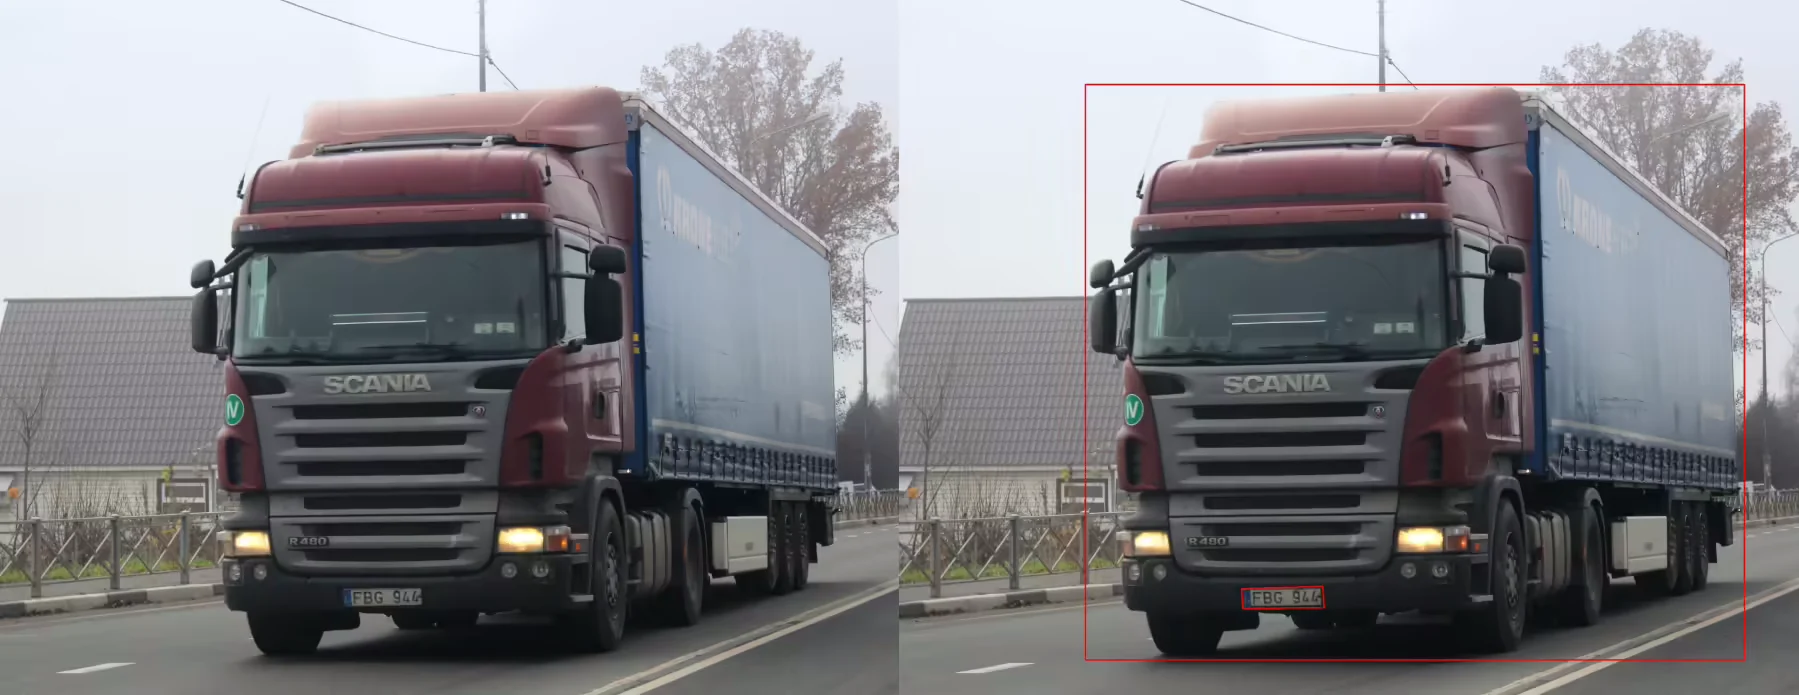
License Plate Annotation for Vehicle Recognition System
- 100,000 images with detailed license plate markup (bounding boxes, digits, regional symbols)
- 3 weeks
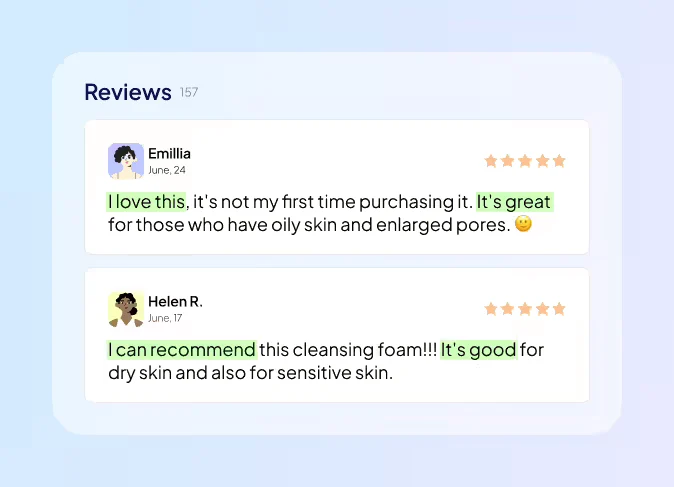
Sentiment Annotation for Brand Monitoring
- Marketing & Consumer Insights
- 12,000 text samples
- 7 weeks
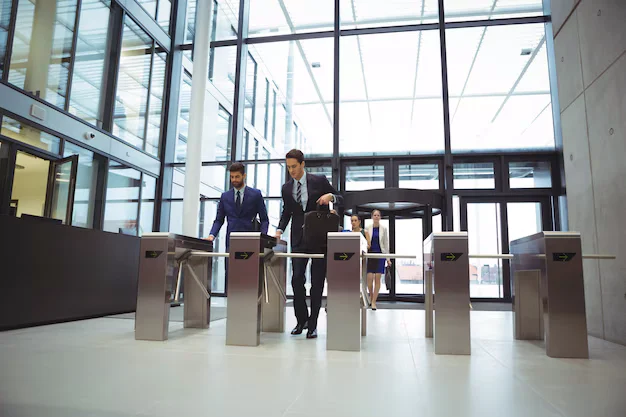
Surveillance Video Annotation for Entrance Monitoring
- Surveillance & Security
- 90 minutes of video from three cameras, approximately 50-60 thousand frames
- 2 week
Similar Datasets
-
 Commercial
- Identity Verification
- Computer Vision
- Machine Learning
- Biometric Recognition
- Security
Human Iris Images Biometric Dataset
High-quality iris dataset with 5,000+ JPG images from 5,000+ individuals, containing left and right eye captures for iris recognition and computer vision tasks. This eye iris dataset includes labeled images collected under visible light, with metadata (ID, eye, sex) to support training data for biometric recognition systems, iris segmentation, and iris pattern analysis.
5,000+ Images
5,000+ People -
Commercial
- Computer Vision
- Machine Learning
- Image Processing
- Security
- Anti-Spoofing
Multi-Material Fingerprint Spoofing Dataset
This fingerprint spoofing dataset contains fingerprint images, captured with a ZKTeco ZK9500 optical scanner and including real fingerprints and spoofing attacks created with alginate, plasticine, and silicone materials. The fingerprint dataset includes metadata (gender, age, finger, hand, device) and supports biometric security research, presentation attack detection, spoof detection, and fingerprint recognition model training.
100 People
4000+ Photos -
Commercial
- Computer Vision
- Machine Learning
- Image Processing
- Security
- Anti-Spoofing
Biometric Fingerprint Spoofing Dataset
Contains 5,000+ high-quality fingerprint images capturing real fingerprints and multiple fingerprint spoofing attack types, including print and replay scenarios. Designed for spoofing detection and liveness detection tasks, the fingerprint dataset provides labeled biometric data from different devices and fingers to train and evaluate biometric security and fingerprint recognition systems.
100 People
5000+ Photos -
Commercial
- Facial Recognition
- Liveness Detection
- Security
- Anti-spoofing
- Computer Vision
Anti-Spoofing Replay PC Videos Dataset
High-quality replay attack dataset containing 4,714 PC-recorded video clips of real faces, designed for training and evaluating face recognition and liveness detection systems. This anti-spoofing videos dataset includes diverse attack scenarios, technical metadata (age, gender, ethnicity), and MP4/MOV formats to support spoofing detection, biometric security, and computer vision model development.
4,714 Videos
4,714 People -
Commercial
- Facial Recognition
- Liveness Detection
- Security
- Anti-spoofing
- Computer Vision
Anti-Spoofing Replay Phone Videos Dataset
This anti-spoofing dataset contains over 40,036 live facial video recordings captured on mobile devices to support replay attack detection and biometric anti-spoofing research. With paired video sets, MP4/MOV formats, and rich metadata such as age, gender, and ethnicity, it provides reliable training data for face antispoofing, liveness detection, and secure biometric authentication systems.
40,036 Videos
20,018 Sets -
Commercial
- Speech Analysis
- ASR
- Machine learning
- Data generation
- Audio Processing
Real vs Fake Human Voice – Deepfake Audio Dataset
Audio dataset containing 5,000 audio files featuring both genuine human recordings and AI-generated voice samples. Each set includes four speakers with multiple clips across M4A and MP3 formats. The dataset supports research in deepfake detection, generated speech analysis, and real vs fake human voice recognition tasks.
5,000 Audio
-
Commercial
- Facial Recognition
- Security
- Anti-spoofing
- Computer Vision
- Machine Learning
Kids Anti-Spoofing Dataset
The dataset provides 6,000 high-quality facial images of children aged 7–15 for face anti-spoofing and liveness detection tasks. This child safety dataset supports research in biometric systems, helping improve facial recognition accuracy, detect spoofing attacks, and build safer AI models for protecting kids in digital and identification environments.
6 000 Images
300 people -
Commercial
- Image Processing
- Machine Learning
- Hand Recognition
- Forensics
- Computer Vision
Open Palm Hand Images Dataset
This high-quality open palm dataset includes 179,052 annotated images collected from 29,842 people, with each set containing six palm photos, two printed-hand images, and two replay videos. Designed for hand recognition and computer vision research, it provides detailed metadata - age, gender, ethnicity, profession, device type, dominant hand, and jewelry status.
179,052 Images
29,842 People -
Commercial
- PII
- Data generation
- Security
- Anti-spoofing
- Computer Vision
Synthetic Printed Turkish Passports Dataset
It is a synthetic Turkish passports dataset containing 5,000 high-quality, AI-generated images. Labeled with detailed metadata - including passport ID, class, gender, and lighting - this dataset supports PII extraction, identity verification, and biometric recognition system training while maintaining strict data protection standards.
5000 Images
-
Commercial
- Facial Recognition
- iBeta
- Liveness Detection
- Security
- Anti-spoofing
- Computer Vision
iBeta Kids Dataset
It is a child safety dataset featuring over 46,000 short video samples of children across different age groups, recorded under varied lighting, devices, and conditions. It includes four main attack types: Real Person, 2D Mask, 3D Mask, and Replay, helping develop biometric systems that detect spoofing and ensure safe, accurate child identification.
45 600 Videos
60 People
Why Companies Trust Unidata's Datasets
Share your project requirements, we handle the rest. Every service is tailored, executed, and compliance-ready, so you can focus on strategy and growth, not operations.

Our Clients Love Us
Ready to get started?
Tell us what you need — we’ll reply within 24h with a free estimate
- Andrew
- Head of Client Success
— I'll guide you through every step, from your first
message to full project delivery
Thank you for your
message
We use cookies to enhance your experience, personalize content, ads, and analyze traffic. By clicking 'Accept All', you agree to our Cookie Policy.