

AI Model Testing Services
Your model scores 98% on your own data. We test it on ours. Independent evaluation on datasets your model has never seen shows what internal benchmarks hide.
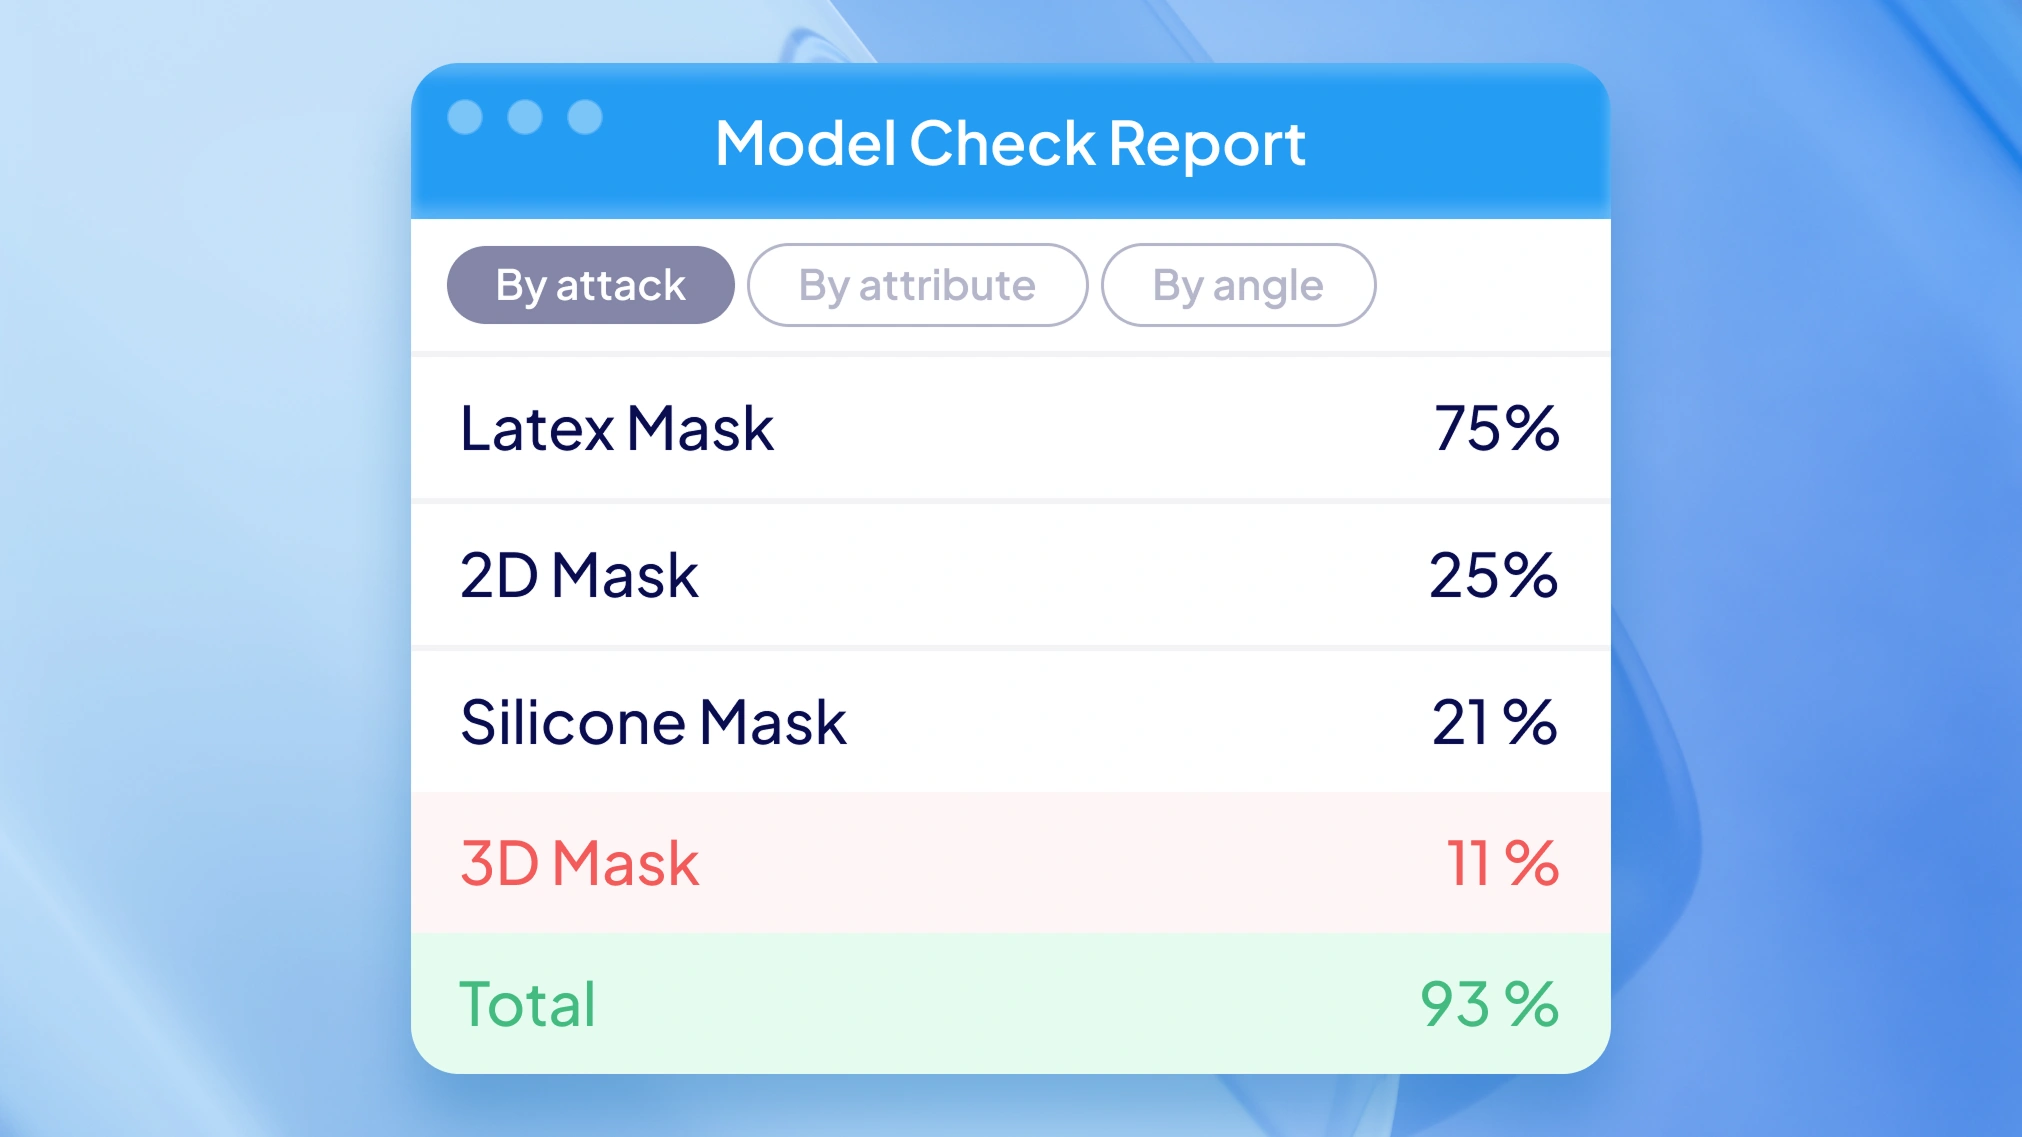
- Every dataset built & owned in-house
- 31 attack classes & 3 bona fide sets
- Error rates per segment, condition & attack class
- One module under NDA is enough to run the audit
AI Model Testing In Numbers
AI Testing Is QA for AI
Your QA team tests the system around the model: contracts, latency, fallbacks, whether the threshold config does what it says. We test the model behind it, with error rates per attack class and per user segment, measured on labeled data it has never seen.
Classic QA
- Expected vs actual outcome
- Acceptance criteria per feature
- Regression suite
- Security testing
AI model testing at unidata
- Labeled ground truth at scale, supplied by us
- Target metrics per module & per segment
- Version-over-version testing on a fixed…
- Presentation attack & deepfake resistance
Why Do You Need AI Model Testing in 2026?
Deployment without an audit
With AI Model Audit from Unidata
Our AI Model Testing Services
One testing infrastructure. Most clients start with AI Model Audit and add the rest as the picture becomes clear
Which Data Your Model Is Tested On
Pick a task to see which sets your model would be measured against, and how large each one is.
-
 Liveness detection & PAD
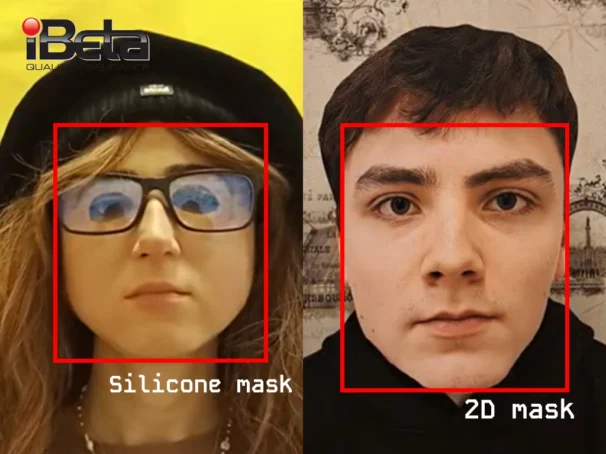
iBeta Level 1 Dataset
35, 800 Videos100% iBeta Level 1 Completion8 Type of AttacksView dataset -
Liveness detection & PAD
iBeta Level 2 Dataset
54,590 Videos100% iBeta Level 2 Completion10 Types of AttacksView dataset -
Liveness detection & PAD
Fabric Masks and Disguise Presentation Attack Dataset
9,090 Videos101 peopleView dataset -
Age verification & estimation
+4
Anti-Spoofing Real Videos Dataset
87,340 Files179 Countries43,670 PeopleView dataset -
Deepfake detection
+1
DeepFake Videos Dataset
5,000 files5,000 peopleView dataset -
Age verification & estimation
+2
Kids Anti-Spoofing Dataset
6 000 Images300 peopleView dataset -
Deepfake detection
+1
Phone and Webcam Video Dataset
30,952 files3869 peopleView dataset -
Face recognition & re-Identification
Medical Masks Dataset
167, 880 Images41, 970 PeopleView dataset -
Age verification & estimation
+2
Kids & Teens Aging Dataset (Ages 7-15)
17,982 Photos1,998 People7-15 AgeView dataset -
Palm recognition
Open Palm Hand Images Dataset
179,052 Images29,842 PeopleView dataset -
Liveness detection & PAD
Anti-Spoofing Replay Phone Videos Dataset
40,036 Videos20,018 SetsView dataset -
Age verification & estimation
+2
iBeta Kids Dataset
45 600 Videos60 PeopleView dataset -
License plate recognition
+1
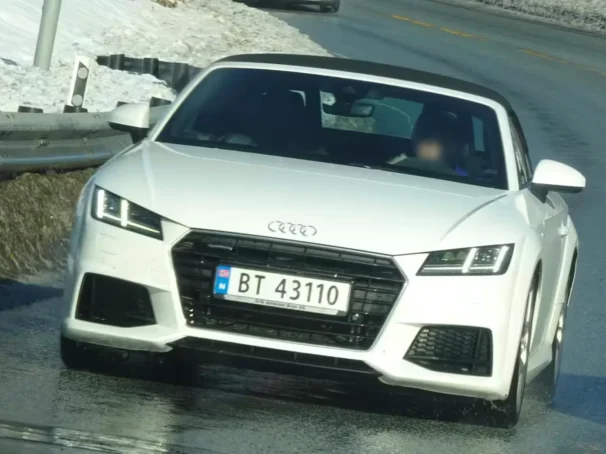
Car License Plate Detection Dataset
1,942,464 images86 CountriesView dataset -
Smart City
France License Plate Detection Dataset
83 752 imagesView dataset -
License plate recognition
Belgium License Plate Detection Dataset
65 166 imagesView dataset -
License plate recognition
Germany License Plate Detection Dataset
83 799 ImagesView dataset -
License plate recognition
Hungary License Plate Detection Dataset
83 708 ImagesView dataset -
License plate recognition
Italy License Plate Detection Dataset
74 600 imagesView dataset -
License plate recognition
Netherlands License Plate Detection Dataset
73 412 imagesView dataset -
License plate recognition
Poland License Plate Detection Dataset
83 793 imagesView dataset -
License plate recognition
Spain License Plate Detection Dataset
83 924 ImagesView dataset -
Smart City
Synthetic USA Driver License Dataset
5 000 ImagesView dataset -
License plate recognition
USA License Plate Detection Dataset
73 384 imagesView dataset -
Deepfake detection
+2
Synthetic Passports Dataset
100 000 Images100+ CountriesView dataset - No results found






How Robust Is Your Training Data?
Lab-tested vs. real-world — not always the same.
Show me what's missingWhat Your Model Is Tested On
Every sample carries metadata, so error rates are reported per attribute and per combination.
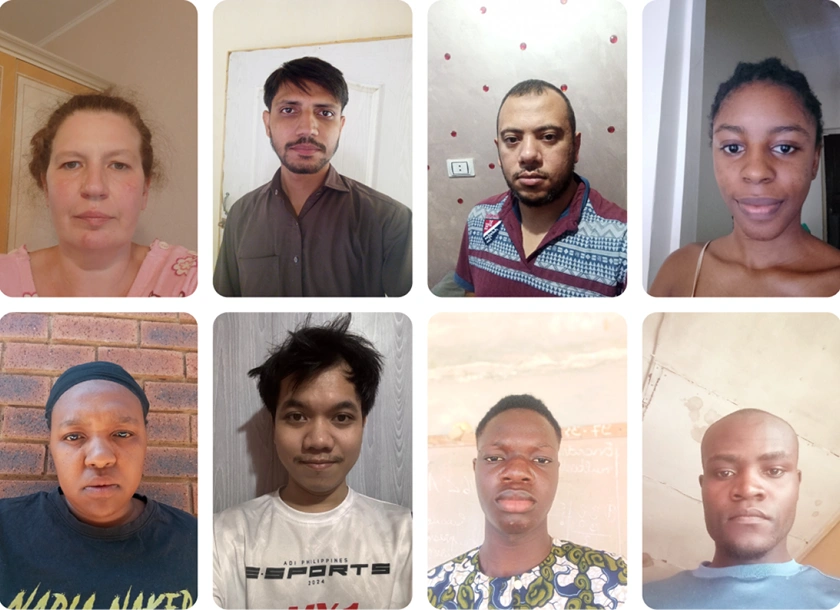
Ethnicity
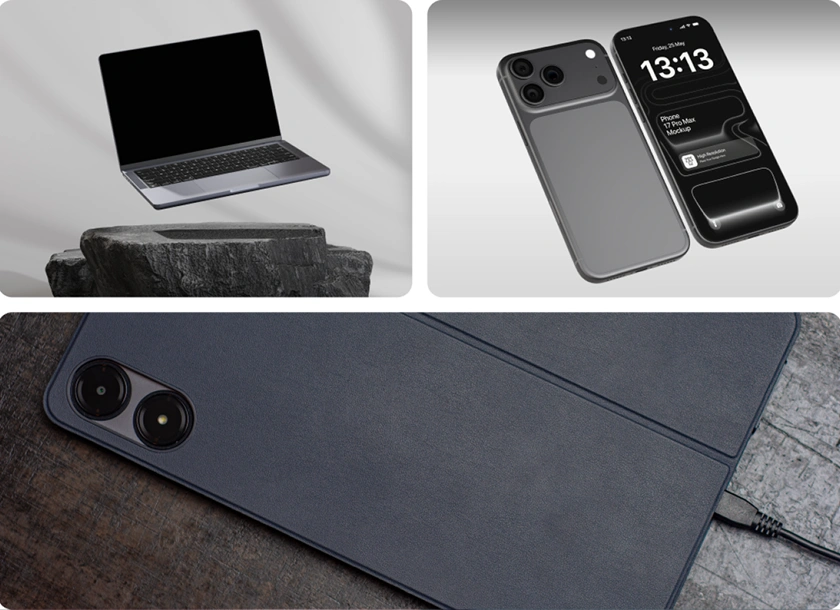
Capture devices
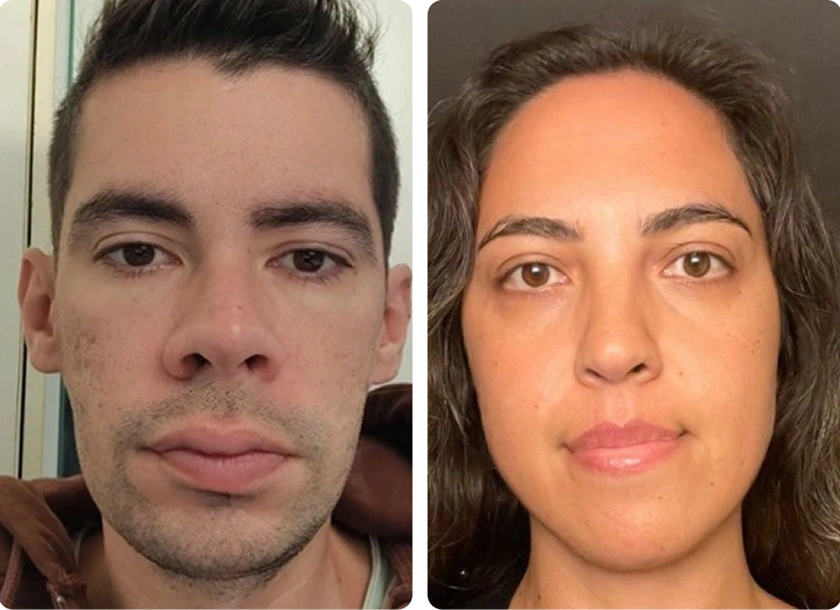
Gender
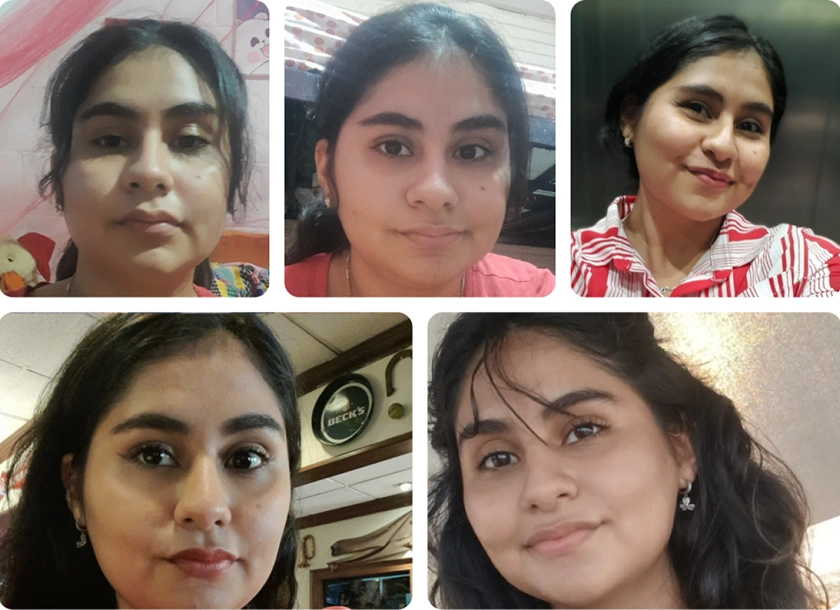
Capture conditions
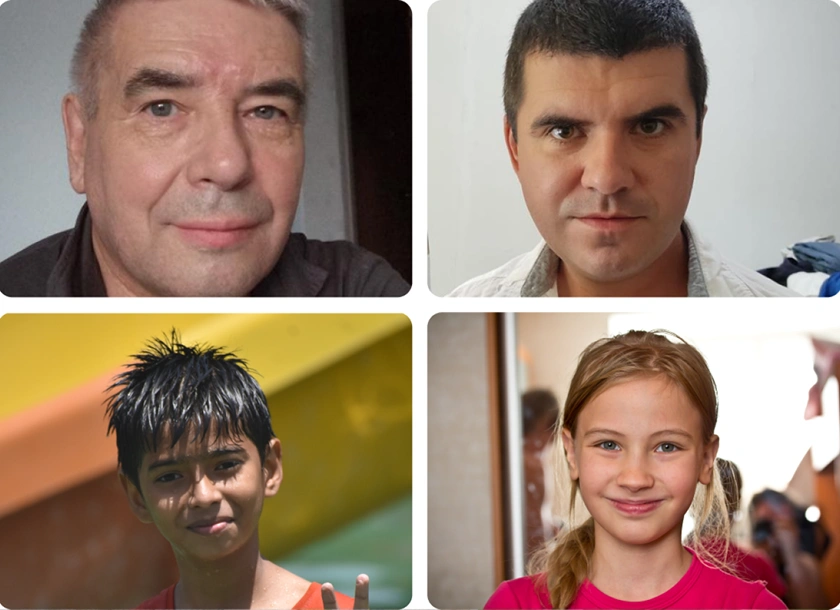
Age
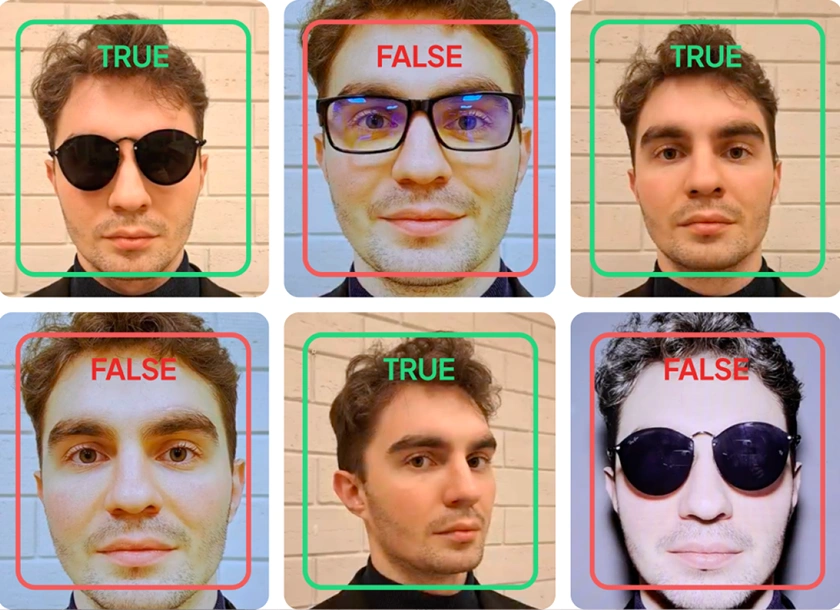
Biometric attacks
Industries We Work With
Identity & Biometrics
Smart City
Documents & OCR
Before You Book iBeta Certification
A lab evaluation is a paid, scheduled, pass-or-fail exam. Run it with us first.
Audit first with unidata, then the lab
Run the audit with Unidata
See what fails, and for whom
Buy only the 5–30% you need
Book the lab once
How the AI Model Audit Process Works at Unidata
Eight steps, two phases, one approval gate between them. Every step is marked with who owns it.
- Together
- We discuss your model, define key metrics such as FAR, FRR and Accuracy, and identify focus areas.
- Together
- Signed before anything leaves your environment. Your IP and the terms of transfer are covered first.
- Together
- You provide access to the module. We return initial results with a timeline and a cost estimate.
- Unidata
- Day 1 covers model & dataset intake. Days 2–5 run your module on our proprietary labeled datasets across every relevant attack class.
- Unidata
- Results analysed across 20+ conditions: demographics, attack types, lighting, devices.
- You
- You review the performance breakdown by segment and condition before anything is final.
- Unidata
- Visualisations, failure modes and recommendations for the model & for data selection.
- You
- You buy only the 5–30% of segments where the model struggles. Diagnosis comes first, data second.
Have questions about the process? Every project starts with a free consultation — no commitment required.
Which Software We Use
Docker for the run, open-source frameworks for the evaluation, Streamlit and Grafana for the report. The checks behind every number are public, documented methods your own ML team can inspect.
The People Who Run Your Audit
Diagnosis Before Data
We do not recommend a dataset before the model has been run. First we find out where it fails, then we look at which data closes that gap. Buying a set because it sounds relevant is how a team spends a quarter and moves the metric by nothing.
- Martinian Letunovsky
- Head of IT Department
The Other Half of Liveness
A liveness model can score well on standard attack datasets and still break on everyday variation: different lighting, glasses, an unusual angle. None of these are attacks, and a real customer is the one who gets rejected. We see this regularly, so we test the genuine-user side as hard as the attack side, with false rejection reported per segment. Turning those customers away is a cost, and it never shows up in a spoof-detection score.
- Elizabeth Karnaukhova
- Project manager, AI model audit
How Your Dashboard Will Look
You open it yourself and read it without us in the room. Every row is a class or a segment, and every number is a rate, not a verdict.
Recommended Data To Close The Gaps
Roughly 12% of our biometric catalogue, selected from what the report above marks red
How We Protect Your Model & IP
Case Study: Liveness Model Audit for Biometric Security
- Biometrics & Face Recognition
- 1000+real-user videos with diverse spoof attacks
- 2 months

FAQ
Ready to get started?
Tell us what you need — we’ll reply within 24h with a free estimate
- Andrew
- Head of Client Success
— I'll guide you through every step, from your first
message to full project delivery
Thank you for your
message
We use cookies to enhance your experience, personalize content, ads, and analyze traffic. By clicking 'Accept All', you agree to our Cookie Policy.