

“We were very happy with the quality of the data that we purchased. It will assist our efforts to improve our product. The team at Unidata was very responsive to our needs, and provided the data format needed to complete our tasks. We are happy to state that Unidata delivers a high quality product in an effective and efficient manner.”
Commercial
British English Speech Recognition Dataset
The dataset consists of 10+ hours of high-quality telephone dialogues from 20+ native speakers in the UK, with detailed annotations (ID, language, format, minutes) to support speech recognition systems, NLP tasks, and machine learning models requiring diverse British English audio datasets.
-
- Speakers
- 20+
-
- Hours
- 10+

- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
The dataset consists of 10+ hours of high-quality telephone dialogues from 20+ native speakers in the UK, with detailed annotations (ID, language, format, minutes) to support speech recognition systems, NLP tasks, and machine learning models requiring diverse British English audio datasets.
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
-
- Speakers
- 20+
-
- Hours
- 10+
Dataset Info
| Characteristic | Data |
| Description | Audio of telephone dialogues in English for training NLP models in real-world conversational scenarios. |
| Data types | Audio |
| Tasks | Speech recognition, NLP |
| Country | The United Kingdom (GBK) |
| Hours of telephone dialogue | 10 |
| Number of speakers | 20 |
| Labeling | Annotation (ID, Language, Format, Minutes) |
| Recording device | Android smartphone, iPhone |

Technical
Characteristics
| Characteristic | Data |
| Audio Format | WAV, M4A, MP3 |
| Recording condition | Low background noise (indoor) |
| Duration | Mean =11 min |
Dataset Use Cases
FAQs
What types of annotations are provided?
This dataset includes transcribed dialogues with metadata such as ID, language, format, minutes.
What are the sources of data for Unidata datasets?
Unidata datasets are created through controlled data collection and trusted partnerships. The dataset was recorded by native speakers on smartphones in indoor conditions with low background noise, ensuring high-quality speech signals.
Is it possible to request a custom dataset?
Yes, Unidata offers custom speech datasets tailored to specific needs. You may request additional English accents, speech samples, or recording conditions to train more accurate speech recognition systems or fine-tuned language models.
Do Unidata datasets follow GDPR or other data privacy regulations?
Yes. Unidata datasets are curated in full compliance with GDPR and international data protection standards. All audio recordings were collected from lawful sources to ensure ethical and responsible data usage.
How are Unidata datasets stored?
All Unidata datasets are securely stored on AWS cloud infrastructure. With ISO 27001 and ISO 27701 certifications, Unidata ensures compliance with international standards for information security and privacy, providing a safe and reliable environment for managing data.
How long does it take to receive the dataset?
Once a request is submitted, Unidata will review the details and finalize the documentation. After the contract is signed and payment is made, a dataset is typically delivered within 3-10 business days.
Is the dataset real-world or synthetic?
This dataset contains real-world audio recordings. It comprises authentic British English telephone dialogues, ensuring natural speech samples for machine learning, NLP tasks, and recognition technology.
How can this dataset help improve voice assistants and conversational AI?
The dataset provides realistic spoken language examples that help AI models recognize everyday British English conversations. It can support the development of voice assistants, transcription services, and dialogue systems that deliver more accurate user interactions.
Still have questions about using Unidata datasets?
Read our user-guides
Unidata Cases
Digital Tree Passport Annotation for Forest Mapping
- Forestry Monitoring & GIS
- 200,000 trees, 10 species classes
- 2 months
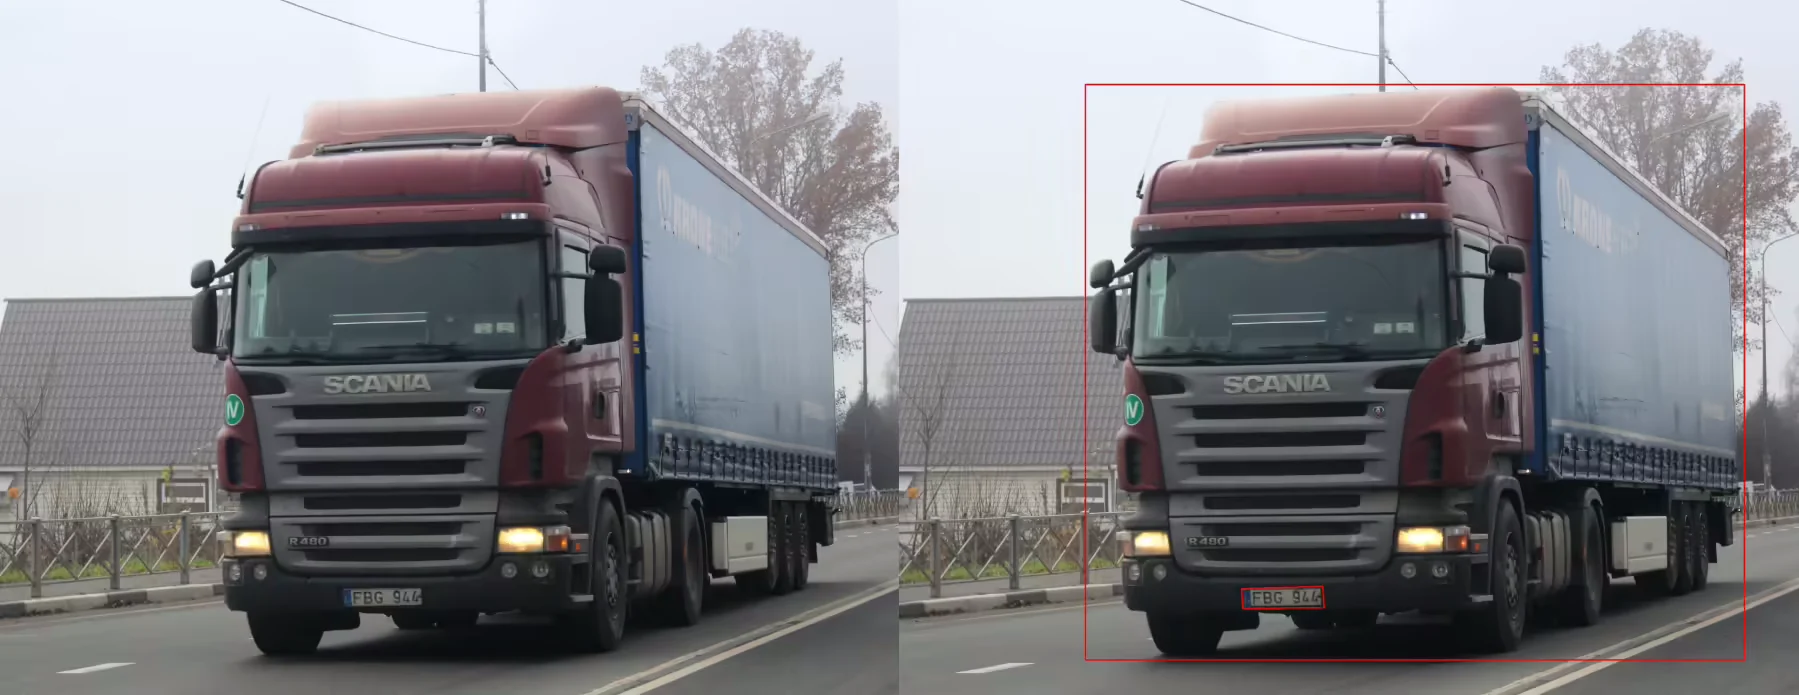
License Plate Annotation for Vehicle Recognition System
- 100,000 images with detailed license plate markup (bounding boxes, digits, regional symbols)
- 3 weeks
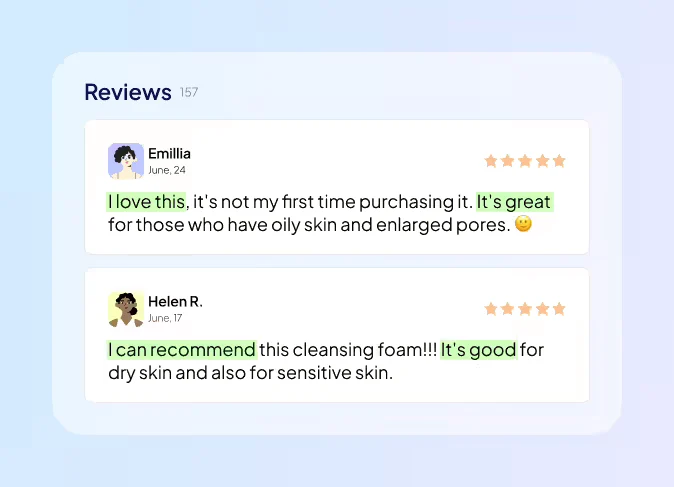
Sentiment Annotation for Brand Monitoring
- Marketing & Consumer Insights
- 12,000 text samples
- 7 weeks
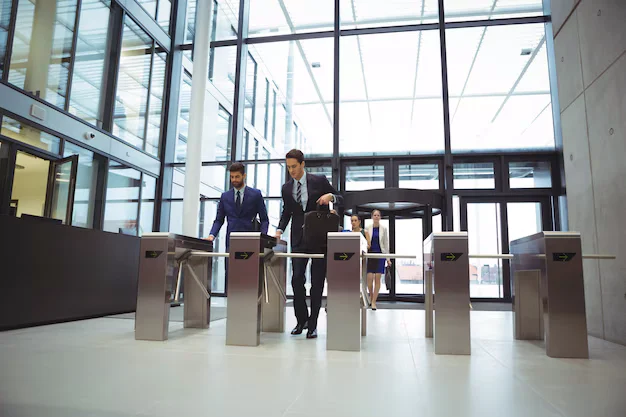
Surveillance Video Annotation for Entrance Monitoring
- Surveillance & Security
- 90 minutes of video from three cameras, approximately 50-60 thousand frames
- 2 week
Similar Datasets
-
 Commercial
- Speech
- Machine Learning
- Audio Processing
- Conversation Analysis
- Medical Audio
Medical Conversations Dataset (English)
It is a large-scale medical conversation dataset with 1,760 hours of audio recordings, featuring audio of medical calls (inbound/outbound), including med device promo, medical dictation, product orders, and patient-doctor conversations, all paired with structured transcripts. This medical speech dataset includes MP3 and WAV formats with JSON and DOCX transcriptions, providing high-quality annotated data.
1760 Hours
-
Commercial
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (Korean)
Human-robot dataset is an audio dataset containing 660+ hours of Korean dialogues between an AI and humans across 20,000 recordings. This conversation dataset includes short
M4A and WAV audio files (up to 2 minutes) with structured metadata, supporting research in human-robot interactions, Korean natural language processing, and AI-driven dialogue systems.660+ Hours
20,000 Files -
Commercial
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (Russian)
Human-robot dataset is an audio dataset containing 660+ hours of Russian dialogues between an AI and humans across 20,000 recordings, created for training conversational AI, speech recognition systems, and language models. This conversation dataset includes short audio sessions (up to 2 minutes) in M4A and OGG formats with structured metadata.
660+ Hours
20,000 Files -
Commercial
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (German)
Human-robot dataset is an audio dataset comprising 660+ hours of German dialogues between an AI and humans across 20,000 recordings, designed for training conversational agents, speech recognition systems, and language models. The conversation dataset includes short audio sessions (up to 2 minutes) in
M4A and WAV formats with structured metadata.660+ Hours
20,000 Files -
Commercial
- Voice Assistant
- ASR
- Machine learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (English)
Human-Robot dataset contains 660+ hours of audio featuring dialogues between AI and a human in English across 20,000 recordings. The dataset supports conversational AI, speech recognition, and human-robot interaction research, with short M4A audio files (up to 2 minutes) and structured metadata for model training.
660+ Hours
20,000 Files -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Slovenian Speech Recognition Dataset
Slovenian speech dataset contains over 10 hours of telephone-recorded dialogues from 20+ native speakers, delivered in MP3 and WAV formats with low background noise and minute-long segments. The dataset includes structured annotations (ID, language, format, duration), making it well-suited for Slovenian speech recognition, spoken language processing, and training language models built on high-quality continuous and spontaneous speech data.
10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Arabic Speech Recognition Dataset
Arabic speech dataset provides over 10 hours of telephone-quality dialogues recorded by
20+ native Arabic speakers from the UAE, offering clean, high-quality audio data suitable for training speech recognition systems, dialogue models, and Arabic language processing tools. The dataset contains annotated audio recordings (ID, language, format, duration) in M4A, MP3, WAV, and AAC, captured with low background noise.10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Vietnamese Speech Recognition Dataset
Vietnamese speech dataset features over 10 hours of telephone-quality audio recordings from native Vietnamese speakers, providing a diverse speech corpus for recognition tasks and training data for NLP models. This Vietnamese audio dataset contains real conversational dialogues with detailed annotations, making it well-suited for machine learning, multi-dialect processing, and benchmarking speech-driven AI systems.
10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Korean Speech Recognition Dataset
This Korean speech dataset provides over 10 hours of telephone-based dialogues recorded by native Korean speakers, offering clean audio data for speech recognition, NLP training, and conversational AI. This Korean audio dataset includes annotated files, consistent recording conditions, and varied dialogue samples, making it a reliable speech corpus for model training and real-world speech detection tasks.
10+ Hours
20+ Speakers -
Commercial
- Classification
- Image Processing
- Machine Learning
- Data Collection
- Data Visualization
Dataset with 30K Illustrations in 20 Artistic Styles
High-quality professional illustrations dataset containing 30,000 images across 20 diverse artistic styles, including 3D, Cartoon, Caricature, Graffiti, and more. The annotated images dataset includes metadata on style, color, keywords, and plot, providing rich training data for image classification, style transfer, and creative machine learning applications.
30,000 images
20 styles
Why Companies Trust Unidata's Datasets
Share your project requirements, we handle the rest. Every service is tailored, executed, and compliance-ready, so you can focus on strategy and growth, not operations.

Our Clients Love Us
Ready to get started?
Tell us what you need — we’ll reply within 24h with a free estimate
- Andrew
- Head of Client Success
— I'll guide you through every step, from your first
message to full project delivery
Thank you for your
message
We use cookies to enhance your experience, personalize content, ads, and analyze traffic. By clicking 'Accept All', you agree to our Cookie Policy.