

“We were very happy with the quality of the data that we purchased. It will assist our efforts to improve our product. The team at Unidata was very responsive to our needs, and provided the data format needed to complete our tasks. We are happy to state that Unidata delivers a high quality product in an effective and efficient manner.”
Commercial
Human-Robot Conversation Dataset (German)
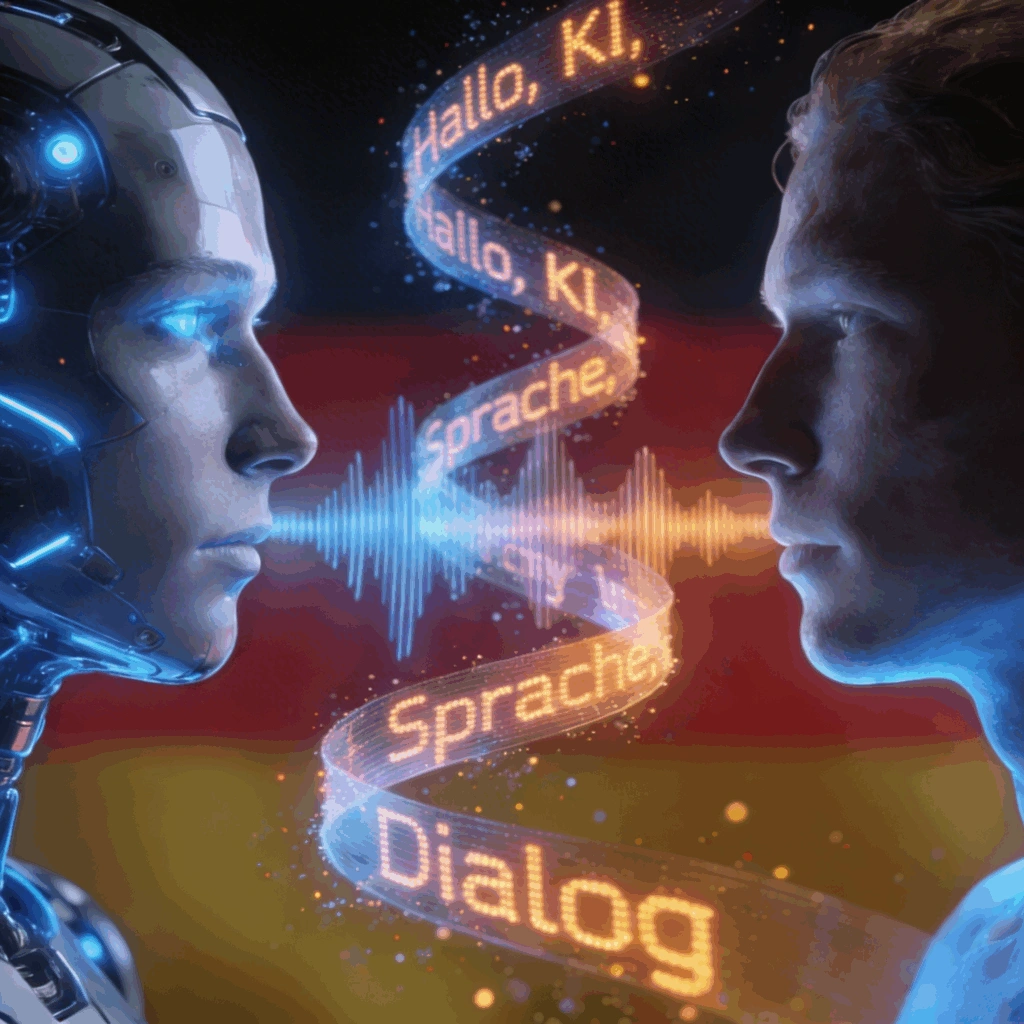
Human-robot dataset is an audio dataset comprising 660+ hours of German dialogues between an AI and humans across 20,000 recordings, designed for training conversational agents, speech recognition systems, and language models. The conversation dataset includes short audio sessions (up to 2 minutes) in M4A and WAV formats with structured metadata.
-
- Hours
- 660+
-
- Files
- 20,000
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-robot dataset is an audio dataset comprising 660+ hours of German dialogues between an AI and humans across 20,000 recordings, designed for training conversational agents, speech recognition systems, and language models. The conversation dataset includes short audio sessions (up to 2 minutes) in M4A and WAV formats with structured metadata.
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
-
- Hours
- 660+
-
- Files
- 20,000
Dataset Info
| Characteristic | Data |
| Description | Audio of German dialogues between AI and humans |
| Data types | Audio |
| Tasks | Speech Recognition, LLM |
| Hours of audio | 660+ |
| Number of sets | 20,000 |
| Language | German |
| Labeling | Metadata (id, language, format) |
Technical
Characteristics
| Characteristic | Data |
| Audio Format | M4A, WAV |
| Duration | Max = 2 min |
Dataset Use Cases
FAQs
What types of annotations are provided in the dataset?
Each audio file includes structured metadata annotations, including file ID, language, and audio format. These annotations help organize the dataset and support efficient data analysis, training dataset preparation, and model evaluation.
What audio formats and technical characteristics are included?
The dataset includes audio recordings in M4A and WAV formats with a maximum duration of approximately two minutes per dialogue file. These standardized formats make the dataset suitable for speech datasets, language processing pipelines, and conversational AI development.
How was the human-robot conversation data collected?
Data was collected through crowdsourcing platforms where participants recorded dialogues simulating human-robot interactions in the German language. This process enables large-scale data collection with varied conversation patterns and realistic speech scenarios.
How are Unidata datasets licensed?
Unidata datasets follow a dual-licensing model. Free samples are provided for testing and evaluation, while complete datasets are available exclusively through purchase.
Do Unidata datasets comply with GDPR and privacy regulations?
Yes, all datasets are curated in compliance with GDPR and applicable data protection laws. Data is collected from legally permissible sources to ensure ethical use in AI development, machine learning, and research applications.
How are Unidata datasets stored?
All datasets are securely stored on AWS cloud infrastructure, ensuring high availability and scalability. Data storage and management follow ISO 27001 and ISO 27701 standards, which provide internationally recognized security and privacy protection.
How long does it take to receive the dataset?
After submitting a request, the Unidata team reviews the details and completes the required documentation. Once the agreement is signed and payment is processed, the dataset is delivered within 3–10 days.
How does conversational audio improve the performance of speech and language models?
Conversational audio provides examples of real communication between users and AI systems, helping models learn dialogue flow and spoken language patterns. This improves speech recognition, response generation, and overall interaction quality.
Still have questions about using Unidata datasets?
Read our user-guides
Unidata Cases
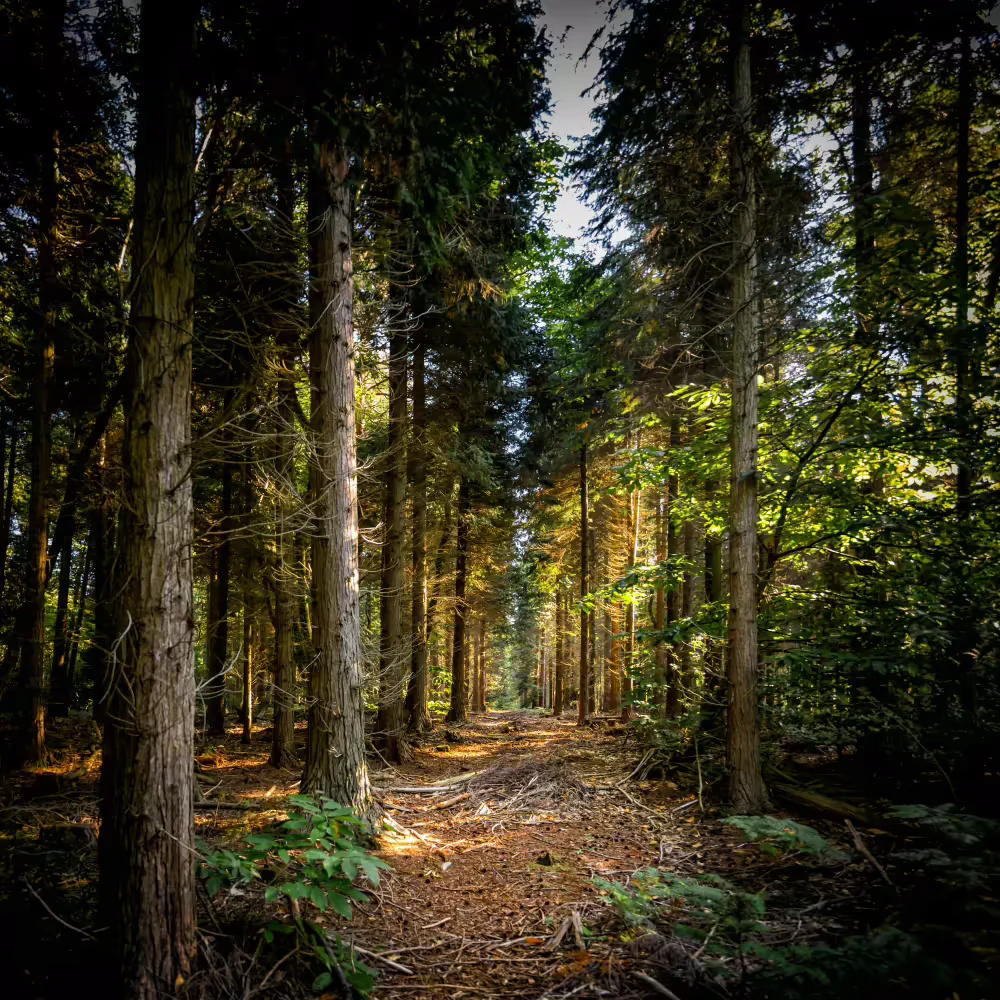
Digital Tree Passport Annotation for Forest Mapping
- Forestry Monitoring & GIS
- 200,000 trees, 10 species classes
- 2 months
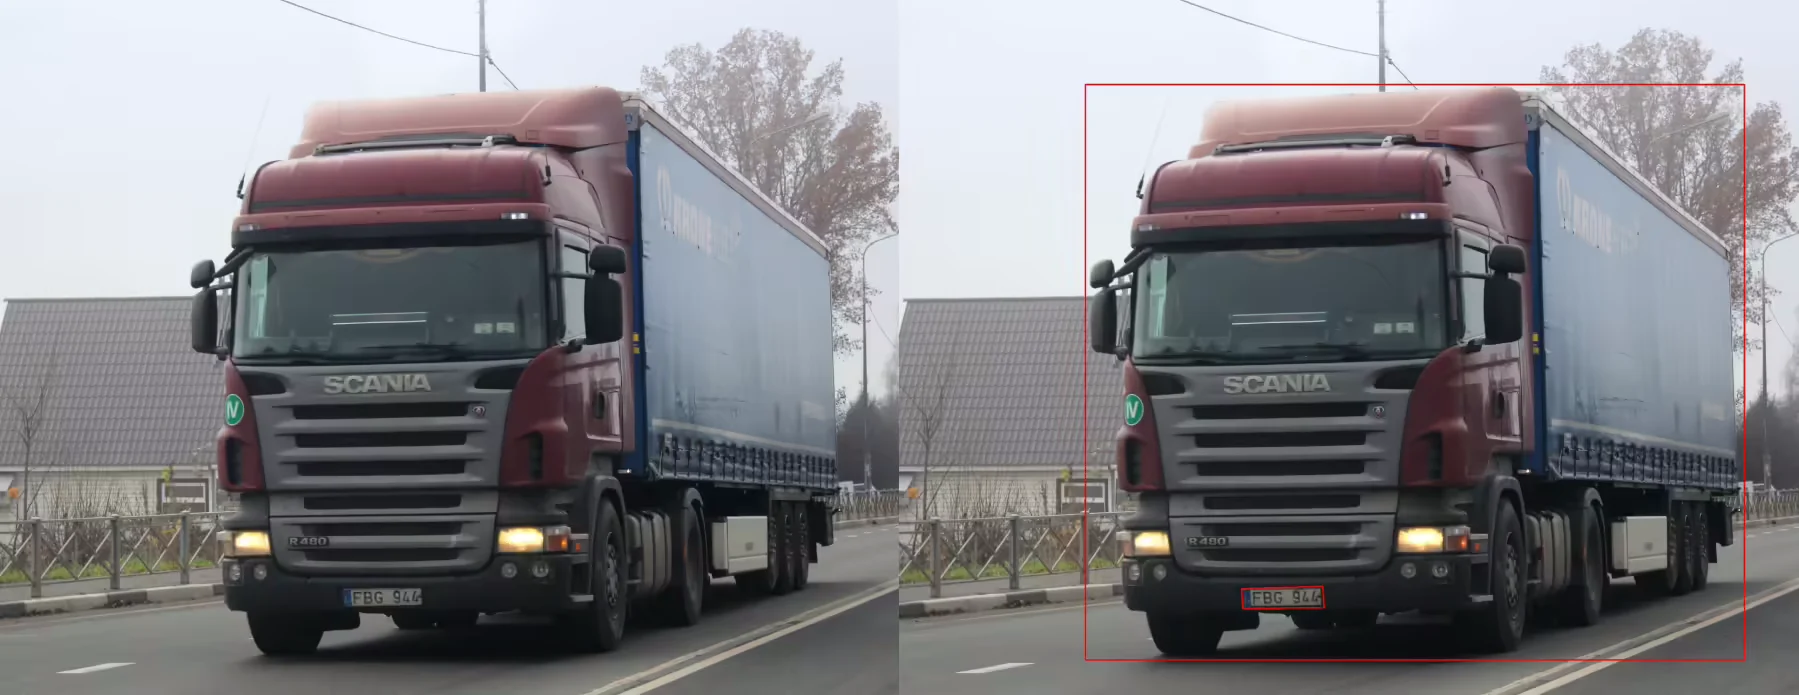
License Plate Annotation for Vehicle Recognition System
- 100,000 images with detailed license plate markup (bounding boxes, digits, regional symbols)
- 3 weeks
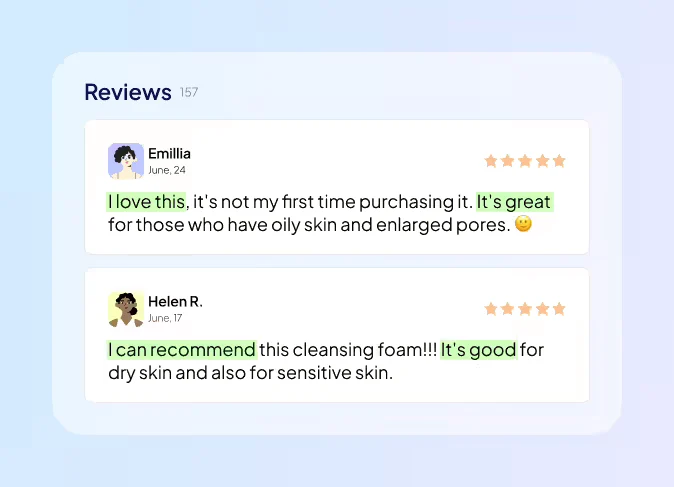
Sentiment Annotation for Brand Monitoring
- Marketing & Consumer Insights
- 12,000 text samples
- 7 weeks
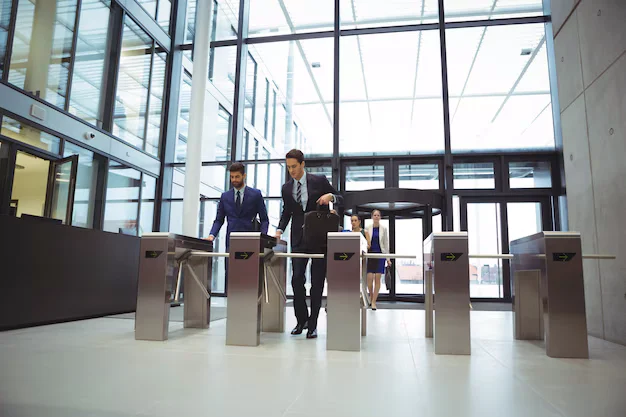
Surveillance Video Annotation for Entrance Monitoring
- Surveillance & Security
- 90 minutes of video from three cameras, approximately 50-60 thousand frames
- 2 week
Similar Datasets
-
 Commercial
- Speech
- Machine Learning
- Audio Processing
- Conversation Analysis
- Medical Audio
Medical Conversations Dataset (English)
It is a large-scale medical conversation dataset with 1,760 hours of audio recordings, featuring audio of medical calls (inbound/outbound), including med device promo, medical dictation, product orders, and patient-doctor conversations, all paired with structured transcripts. This medical speech dataset includes MP3 and WAV formats with JSON and DOCX transcriptions, providing high-quality annotated data.
1760 Hours
-
Commercial
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (Korean)
Human-robot dataset is an audio dataset containing 660+ hours of Korean dialogues between an AI and humans across 20,000 recordings. This conversation dataset includes short
M4A and WAV audio files (up to 2 minutes) with structured metadata, supporting research in human-robot interactions, Korean natural language processing, and AI-driven dialogue systems.660+ Hours
20,000 Files -
Commercial
- Voice Assistant
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (Russian)
Human-robot dataset is an audio dataset containing 660+ hours of Russian dialogues between an AI and humans across 20,000 recordings, created for training conversational AI, speech recognition systems, and language models. This conversation dataset includes short audio sessions (up to 2 minutes) in M4A and OGG formats with structured metadata.
660+ Hours
20,000 Files -
Commercial
- Voice Assistant
- ASR
- Machine learning
- Audio Processing
- Voice Recognition
Human-Robot Conversation Dataset (English)
Human-Robot dataset contains 660+ hours of audio featuring dialogues between AI and a human in English across 20,000 recordings. The dataset supports conversational AI, speech recognition, and human-robot interaction research, with short M4A audio files (up to 2 minutes) and structured metadata for model training.
660+ Hours
20,000 Files -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Slovenian Speech Recognition Dataset
Slovenian speech dataset contains over 10 hours of telephone-recorded dialogues from 20+ native speakers, delivered in MP3 and WAV formats with low background noise and minute-long segments. The dataset includes structured annotations (ID, language, format, duration), making it well-suited for Slovenian speech recognition, spoken language processing, and training language models built on high-quality continuous and spontaneous speech data.
10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Arabic Speech Recognition Dataset
Arabic speech dataset provides over 10 hours of telephone-quality dialogues recorded by
20+ native Arabic speakers from the UAE, offering clean, high-quality audio data suitable for training speech recognition systems, dialogue models, and Arabic language processing tools. The dataset contains annotated audio recordings (ID, language, format, duration) in M4A, MP3, WAV, and AAC, captured with low background noise.10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Vietnamese Speech Recognition Dataset
Vietnamese speech dataset features over 10 hours of telephone-quality audio recordings from native Vietnamese speakers, providing a diverse speech corpus for recognition tasks and training data for NLP models. This Vietnamese audio dataset contains real conversational dialogues with detailed annotations, making it well-suited for machine learning, multi-dialect processing, and benchmarking speech-driven AI systems.
10+ Hours
20+ Speakers -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Korean Speech Recognition Dataset
This Korean speech dataset provides over 10 hours of telephone-based dialogues recorded by native Korean speakers, offering clean audio data for speech recognition, NLP training, and conversational AI. This Korean audio dataset includes annotated files, consistent recording conditions, and varied dialogue samples, making it a reliable speech corpus for model training and real-world speech detection tasks.
10+ Hours
20+ Speakers -
Commercial
- Classification
- Image Processing
- Machine Learning
- Data Collection
- Data Visualization
Dataset with 30K Illustrations in 20 Artistic Styles
High-quality professional illustrations dataset containing 30,000 images across 20 diverse artistic styles, including 3D, Cartoon, Caricature, Graffiti, and more. The annotated images dataset includes metadata on style, color, keywords, and plot, providing rich training data for image classification, style transfer, and creative machine learning applications.
30,000 images
20 styles -
Commercial
- NLP
- LLM
- Machine Learning
- Audio Processing
- ASR
- Voice Recognition
Portuguese Speech Recognition Dataset
The dataset contains 10+ hours of annotated telephone dialogues from 20+ native Portuguese speakers, offering detailed audio recordings, transcriptions, and speaker metadata to train speech recognition systems, NLP models, and machine learning applications with diverse Portuguese speech datasets
10+ Hours
20+ Speakers
Why Companies Trust Unidata's Datasets
Share your project requirements, we handle the rest. Every service is tailored, executed, and compliance-ready, so you can focus on strategy and growth, not operations.
Our Clients Love Us
Ready to get started?
Tell us what you need — we’ll reply within 24h with a free estimate
We partnered with Unidata for a vast collection of webcam and smartphone assets and were very satisfied. The data quality was excellent, maintaining high resolution and clarity across all formats to meet our specific technical needs. The procurement process was seamless thanks to their customer service. The team was proactive and transparent, ensuring smooth communication from start to finish. Although the investment was significant, the professional caliber of the data and the reliability of the service made it a worthwhile value.
Trusted by the market's leading brands

Thank you for your
message
We use cookies to enhance your experience, personalize content, ads, and analyze traffic. By clicking 'Accept All', you agree to our Cookie Policy.