

“We were very happy with the quality of the data that we purchased. It will assist our efforts to improve our product. The team at Unidata was very responsive to our needs, and provided the data format needed to complete our tasks. We are happy to state that Unidata delivers a high quality product in an effective and efficient manner.”
Commercial
Call Center Audio Dataset
Call center dataset containing 13,000+ hours of real-world customer service calls from global call centers, featuring 90%+ unique speakers and time-stamped transcripts. The dataset includes high-quality call center data with rich metadata and multilingual conversations, enabling businesses and researchers to analyze customer interactions, perform sentiment analysis, and improve customer support.
-
- Hours
- 13,000+
-
- Unique Speakers
- 90%+
- Speech Analysis
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
- Speech Analysis
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
Call center dataset containing 13,000+ hours of real-world customer service calls from global call centers, featuring 90%+ unique speakers and time-stamped transcripts. The dataset includes high-quality call center data with rich metadata and multilingual conversations, enabling businesses and researchers to analyze customer interactions, perform sentiment analysis, and improve customer support.
- Speech Analysis
- ASR
- Machine Learning
- Audio Processing
- Voice Recognition
-
- Hours
- 13,000+
-
- Unique Speakers
- 90%+
Dataset Info
| Characteristic | Data |
| Description | Audio of real customer service calls |
| Data types | Audio |
| Tasks | Speech Recognition, Speaker Diarization |
| Hours of audio | 13,000+ |
| Language | English: 96%, Spanish: 2.5%, Hindi: 1%, Other languages: 0.5% |
| Labeling | Metadata (id, company, category, device, OS, city, state, country, duration, wait time, transcription, AI summary) |
Technical
Characteristics
| Characteristic | Data |
| Audio Format | OGG, FLAC |
| Duration | Mean = ~770 seconds (~13 minutes) |
Dataset Use Cases
FAQs
Can I request a sample of the call center dataset before purchasing?
Yes, a sample of the call center dataset can be requested for evaluation purposes. This allows teams to review the structure of the audio files, transcripts, and metadata before integrating the full customer service dataset into their training pipelines.
What types of annotations are provided with the dataset?
Each audio file includes structured metadata such as company category, device, operating system, geographic location, call duration, and wait time. The dataset also contains transcriptions and AI-generated summaries.
How are Unidata datasets licensed?
Unidata datasets follow a dual-licensing model. Free samples are available for testing and validation, while full datasets containing large volumes of audio data are provided through purchase.
Do Unidata datasets comply with GDPR and other privacy regulations?
Yes, all datasets are curated in compliance with GDPR and applicable data protection laws. Data is obtained from legally permissible sources to ensure ethical use in AI research and machine learning development.
How are Unidata datasets stored?
All datasets are stored securely on AWS cloud infrastructure, ensuring reliability and scalability. Storage and management processes follow ISO 27001 and ISO 27701 standards, providing a secure environment for handling large audio datasets and associated metadata.
How long does it take to receive the dataset?
After submitting a request, the Unidata team reviews the requirements and completes the necessary documentation. Once the agreement is signed and payment is processed, the dataset is typically delivered within 3–10 days.
Why is real customer conversation data valuable for speech recognition models?
Real customer calls contain natural speech variations, spontaneous dialogue, and diverse communication styles. Training AI models on authentic conversations helps improve accuracy when processing real-world customer interactions.
Is this dataset real-world or synthetic?
This dataset consists entirely of real-world customer service call recordings captured during actual interactions between customers and agents. The audio data is fully licensed, non-synthetic, and reflects communication patterns found in modern call centers.
Why are transcripts and metadata important for conversational AI training?
Structured transcripts and metadata help AI systems connect spoken content with additional context, making it easier to train and evaluate models. This supports more accurate speech processing, conversation analysis, and automation workflows.
Still have questions about using Unidata datasets?
Read our user-guides
Unidata Cases
Digital Tree Passport Annotation for Forest Mapping
- Forestry Monitoring & GIS
- 200,000 trees, 10 species classes
- 2 months
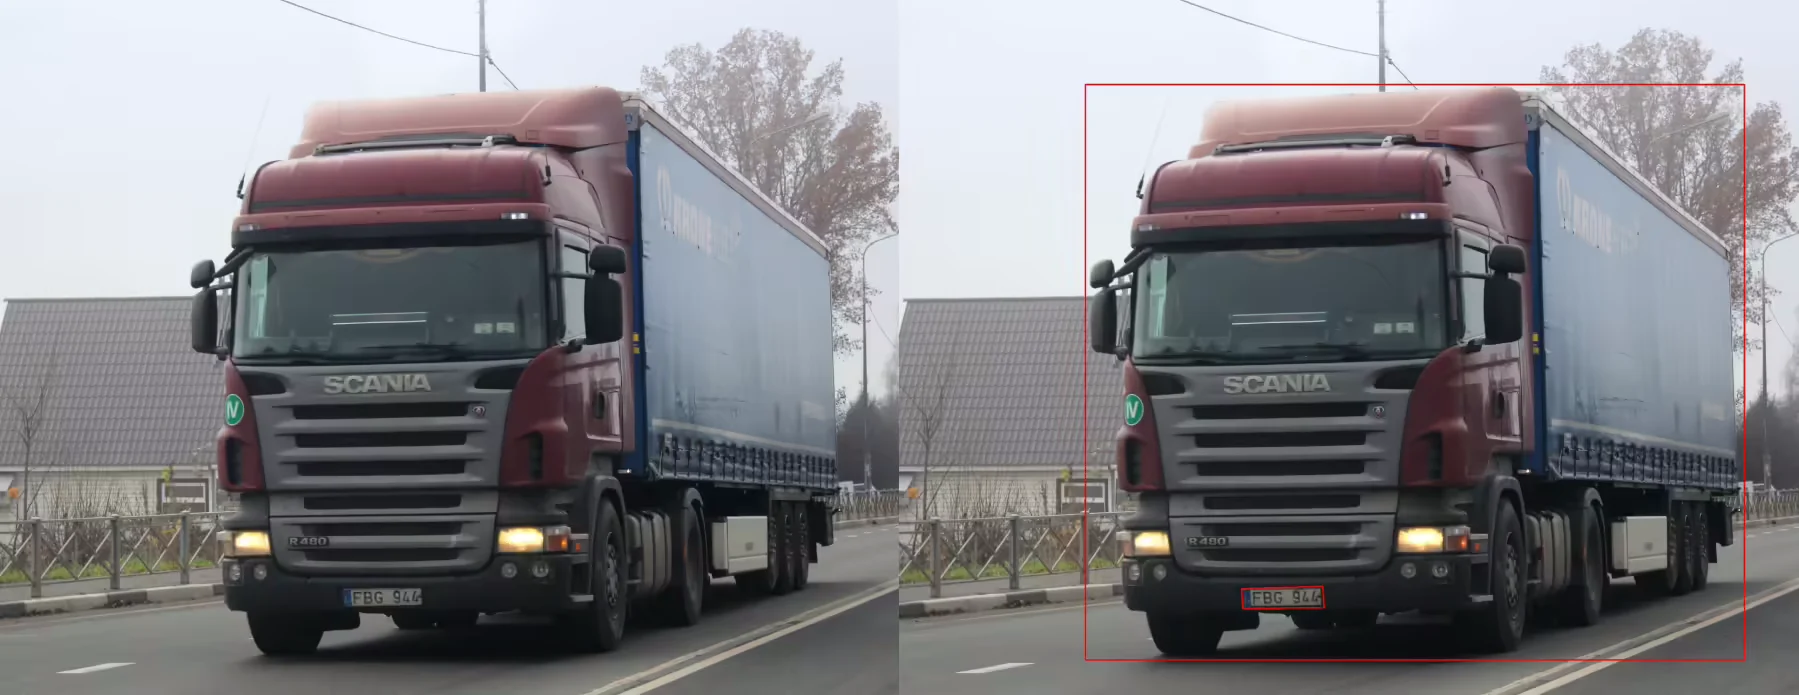
License Plate Annotation for Vehicle Recognition System
- 100,000 images with detailed license plate markup (bounding boxes, digits, regional symbols)
- 3 weeks
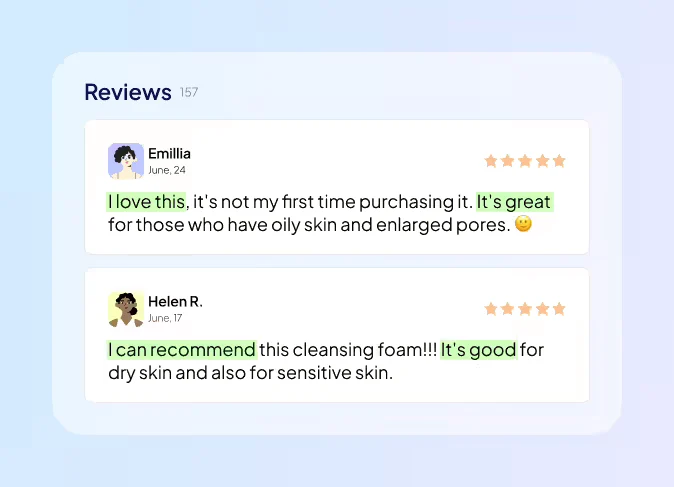
Sentiment Annotation for Brand Monitoring
- Marketing & Consumer Insights
- 12,000 text samples
- 7 weeks
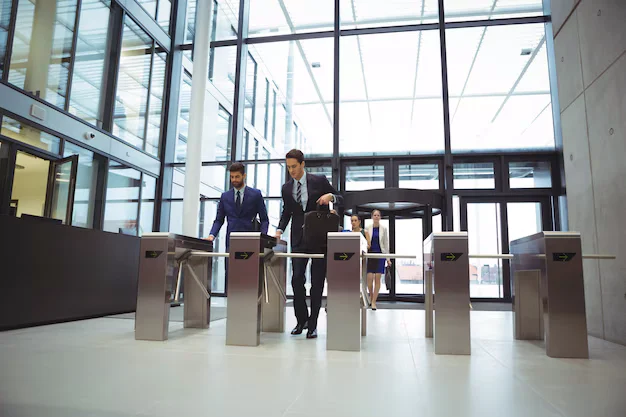
Surveillance Video Annotation for Entrance Monitoring
- Surveillance & Security
- 90 minutes of video from three cameras, approximately 50-60 thousand frames
- 2 week
Similar Datasets
Why Companies Trust Unidata's Datasets
Share your project requirements, we handle the rest. Every service is tailored, executed, and compliance-ready, so you can focus on strategy and growth, not operations.

Our Clients Love Us
Ready to get started?
Tell us what you need — we’ll reply within 24h with a free estimate
- Andrew
- Head of Client Success
— I'll guide you through every step, from your first
message to full project delivery
Thank you for your
message
We use cookies to enhance your experience, personalize content, ads, and analyze traffic. By clicking 'Accept All', you agree to our Cookie Policy.